-
Cooperative-Competitive Autonomous Racing through Joint Latent Imagination
Introduction Multi-agent autonomous racing requires agents to balance individual performance, cooperation with teammates and competition against opponents. In a 2-vs-2 setting, effective decisions may involve coordinated overtaking, defensive blocking or sacrificing short-term individual performance to improve the team outcome. Model-based reinforcement learning provides a promising framework for this problem by learning a predictive world model and optimizing policies through imagined multi-agent trajectories. This thesis investigates joint latent imagination for 2-vs-2 autonomous racing, with the goal of learning coordinated team strategies without relying on an explicitly designed high-level tactical planner. Goals Requirements Contact Marco Doria Fragomeni: marco.doria@polimi.itStefano Arrigoni: stefano.arrigoni@polimi.it Read more
-
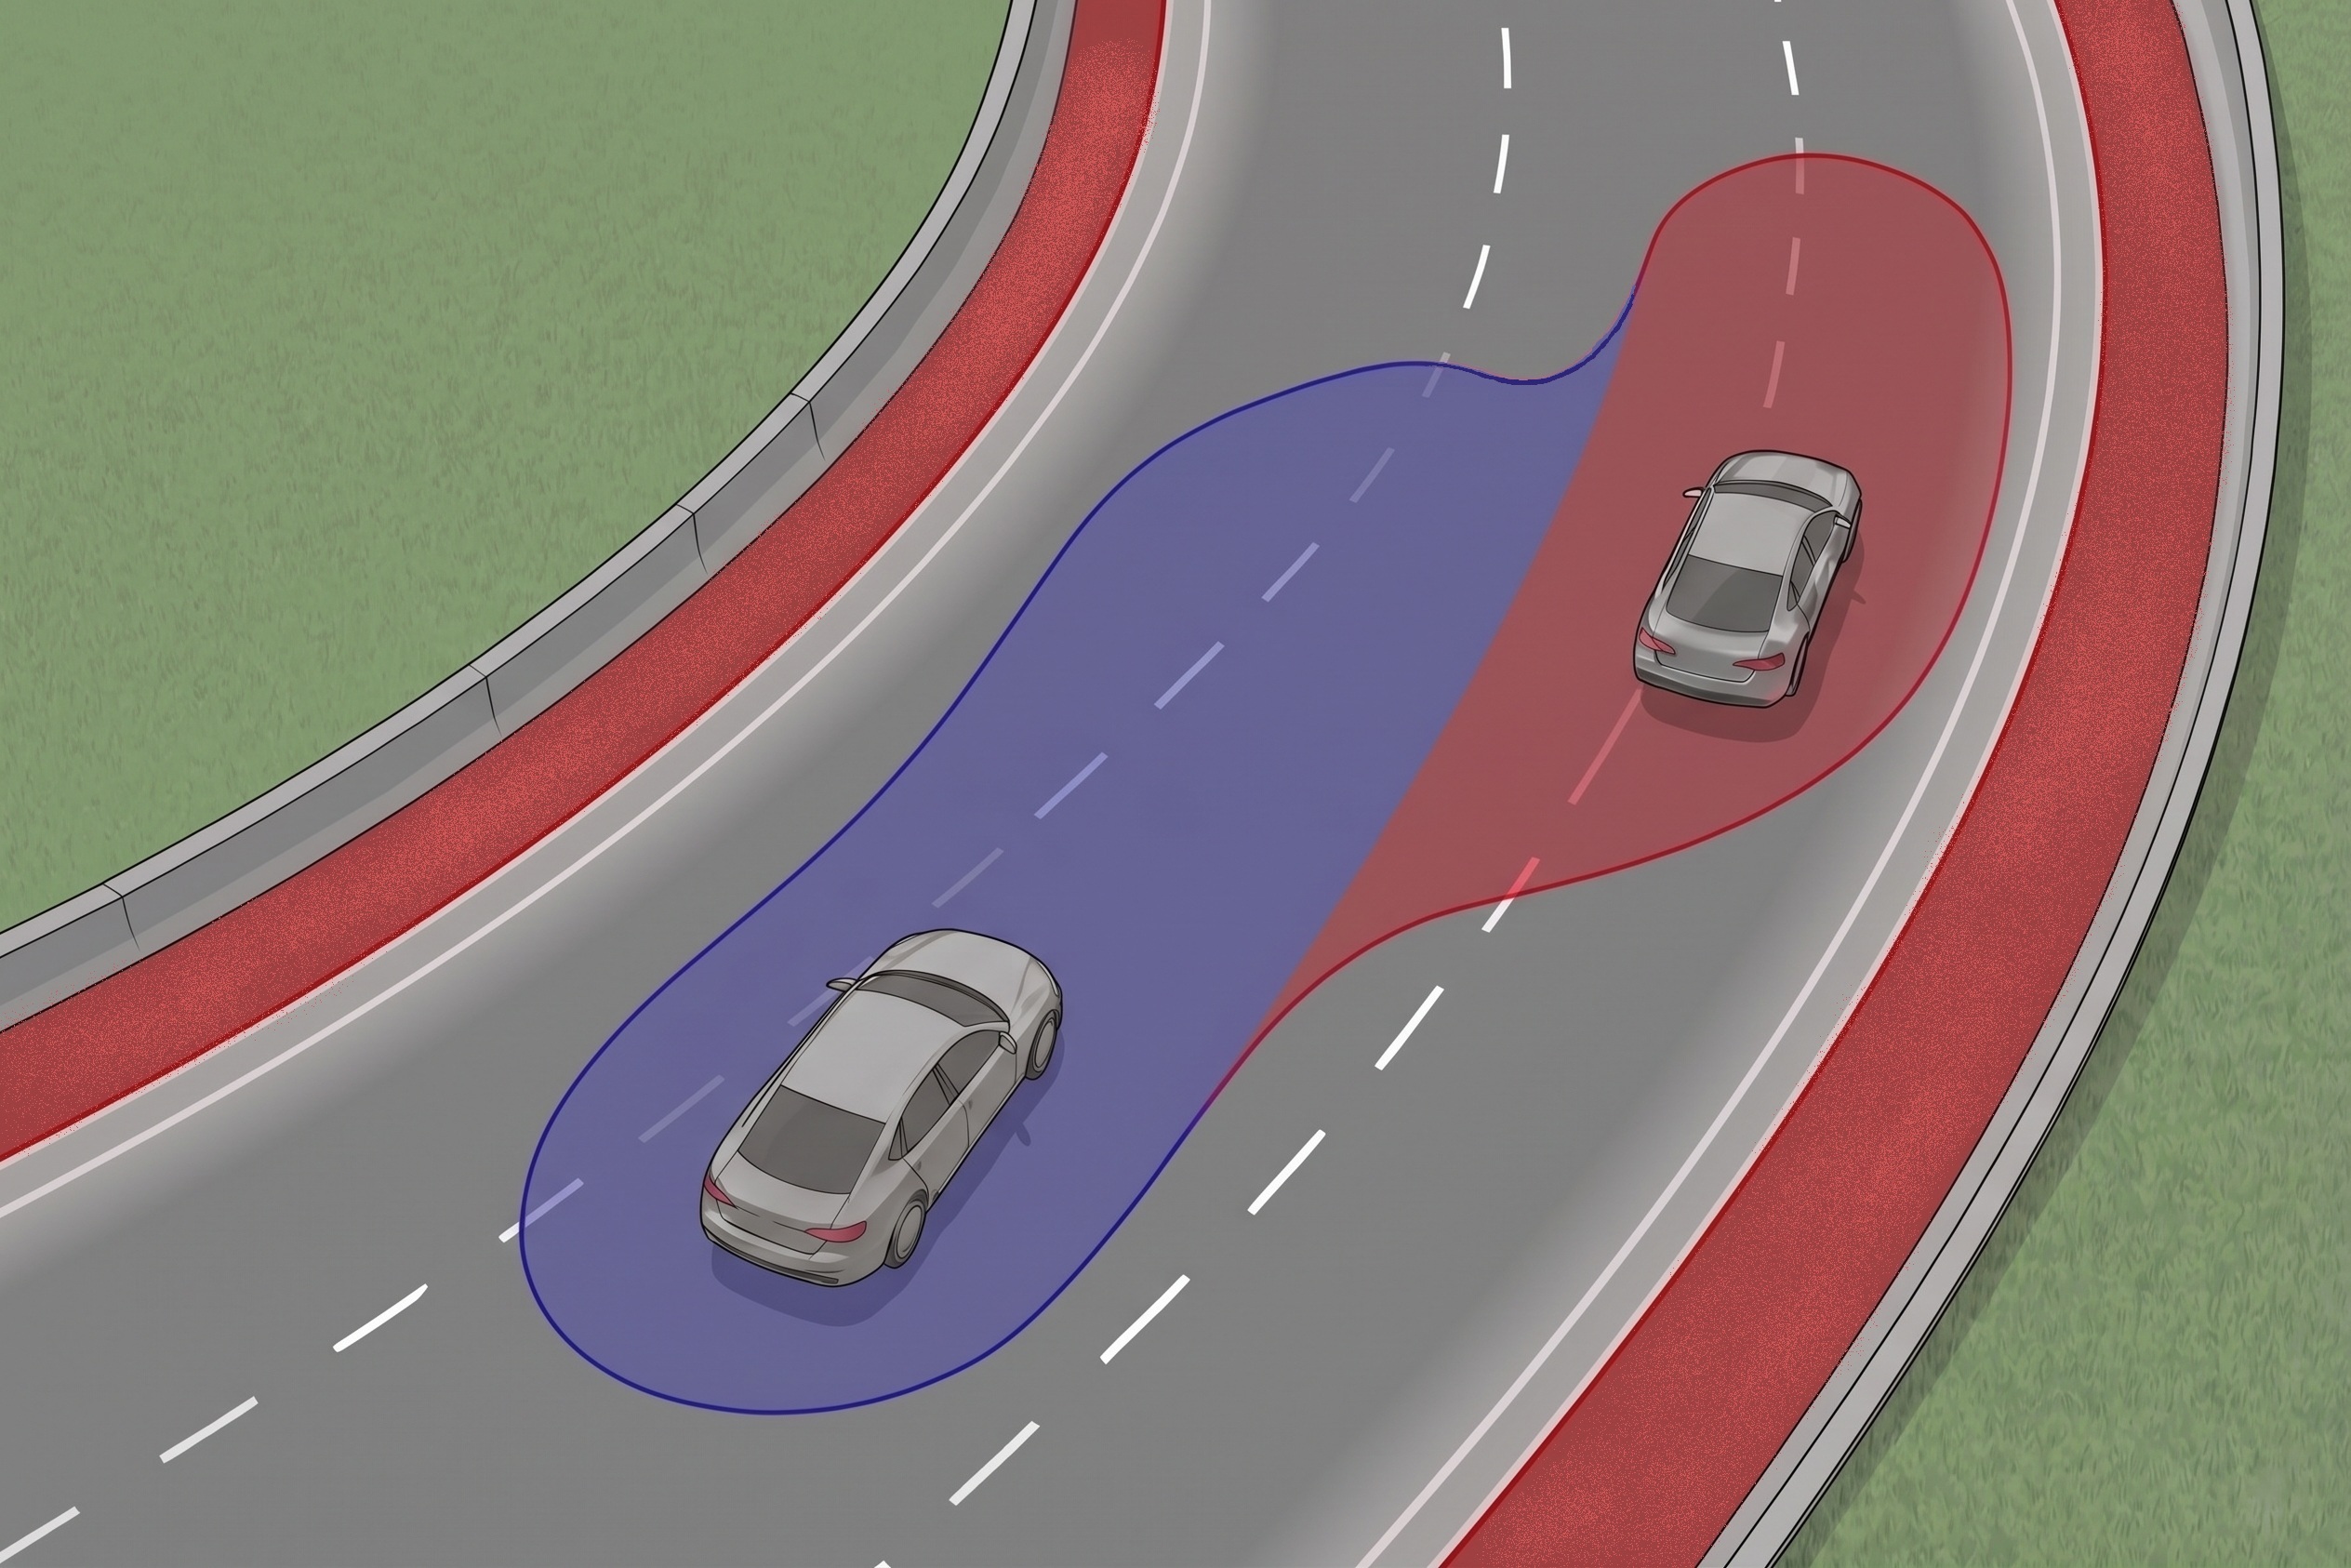
Environment-Aware Collision Avoidance for Multi-Agent Navigation
Introduction Safe autonomous navigation requires reasoning not only about how other agents may move, but also about which maneuvers are compatible with the surrounding environment. Hamilton–Jacobi (HJ) reachability can provide a framework for collision avoidance under worst-case interactions. Environmental constraints can already be included in HJ formulations, but combining geometry and multi-agent interaction can significantly increase problem dimensionality. Standard pairwise formulations may also consider maneuvers that are feasible in open space but incompatible with the actual environment. This thesis investigates how environmental geometry can be incorporated into HJ differential games and whether environmental and interaction safety can be handled separately… Read more
-

Reduced-order aeroelastic modeling and control of inflatable multirotor drones
Inflatable and soft structures offer interesting opportunities for the development of lightweight, compact, and deployable aerial vehicles. In particular, multirotor drones based on inflatable structural frames could combine conventional propulsion and control systems with lightweight and compliant supporting structures. Such configurations may enable drones that can be compactly stored and rapidly deployed, while also providing increased robustness to impacts and collisions. The structural compliance of an inflatable frame, however, introduces important interactions between structural deformation and flight dynamics. Rotor thrust loads may deform the inflatable arms, modifying the position and orientation of the rotors and therefore the forces and moments… Read more
-
Bridging Simulation and Reality for Autonomous Underwater Vehicles
Autonomous Underwater Vehicles (AUV) are subject to highly non-linear hydrodynamic forces, significant parametric uncertainty, and unpredictable environmental disturbances, all of which make robust low-level control a persistent open challenge. This thesis investigates control strategies for AUV motion control with a focus on robustness, the ability of a controller to maintain acceptable performance despite uncertainty in vehicle parameters and environmental conditions. The work begins with a survey of available simulation environments for AUV dynamics, characterising how different tools model hydrodynamic effects and how their predictions diverge under parameter variations. Building on this, a systematic study of parametric uncertainty is conducted, varying… Read more
-
Fall Recovery for Quadrupeds
Introduction Legged robots operating in real-world environments are inevitably exposed to disturbances, uneven terrain, and interaction forces that can lead to loss of balance and falls. Robust fall recovery is therefore a critical capability for enabling truly autonomous deployment of quadruped robots in unstructured settings. While traditional approaches rely on hand-crafted reflexes or carefully engineered controllers, these methods often struggle to generalize beyond a narrow set of scenarios. In this thesis, we propose to investigate Reinforcement Learning (RL) methods for fall recovery in quadruped robots. The core idea is to learn feedback policies that, given a potentially high-impact post-fall state… Read more
-

Fall Recovery for Humanoid Robots
Introduction Humanoid robots are designed to operate in human-centered environments, where unexpected contacts, uneven terrain, and external disturbances frequently lead to loss of balance and falls. Reliable fall recovery is therefore a key capability for long-term autonomous operation and human–robot coexistence. Classical approaches rely on carefully engineered whole-body controllers and pre-defined get-up sequences, which are often tailored to a specific robot morphology and a limited set of fall configurations, making generalization difficult. In this thesis, we propose to investigate Reinforcement Learning (RL) methods for fall recovery in humanoid robots. The core idea is to learn whole-body control policies that, starting… Read more
-
Actuator Modeling
Introduction Recent advances in GPU-based physics simulation and deep Reinforcement Learning (RL) have enabled the rapid training of control policies for complex, highly articulated robots such as quadrupeds and humanoids. Parallelized simulators now make it possible to obtain policies that transfer to hardware in a matter of minutes of simulated experience [1]. Despite this progress, a significant discrepancy often remains between performance in simulation and on the real robot, commonly referred to as the Sim2Real gap. This gap arises from several sources along the RL control pipeline [2, 3, 4]. First, the reality gap captures mismatches between simulated and real-world… Read more
-
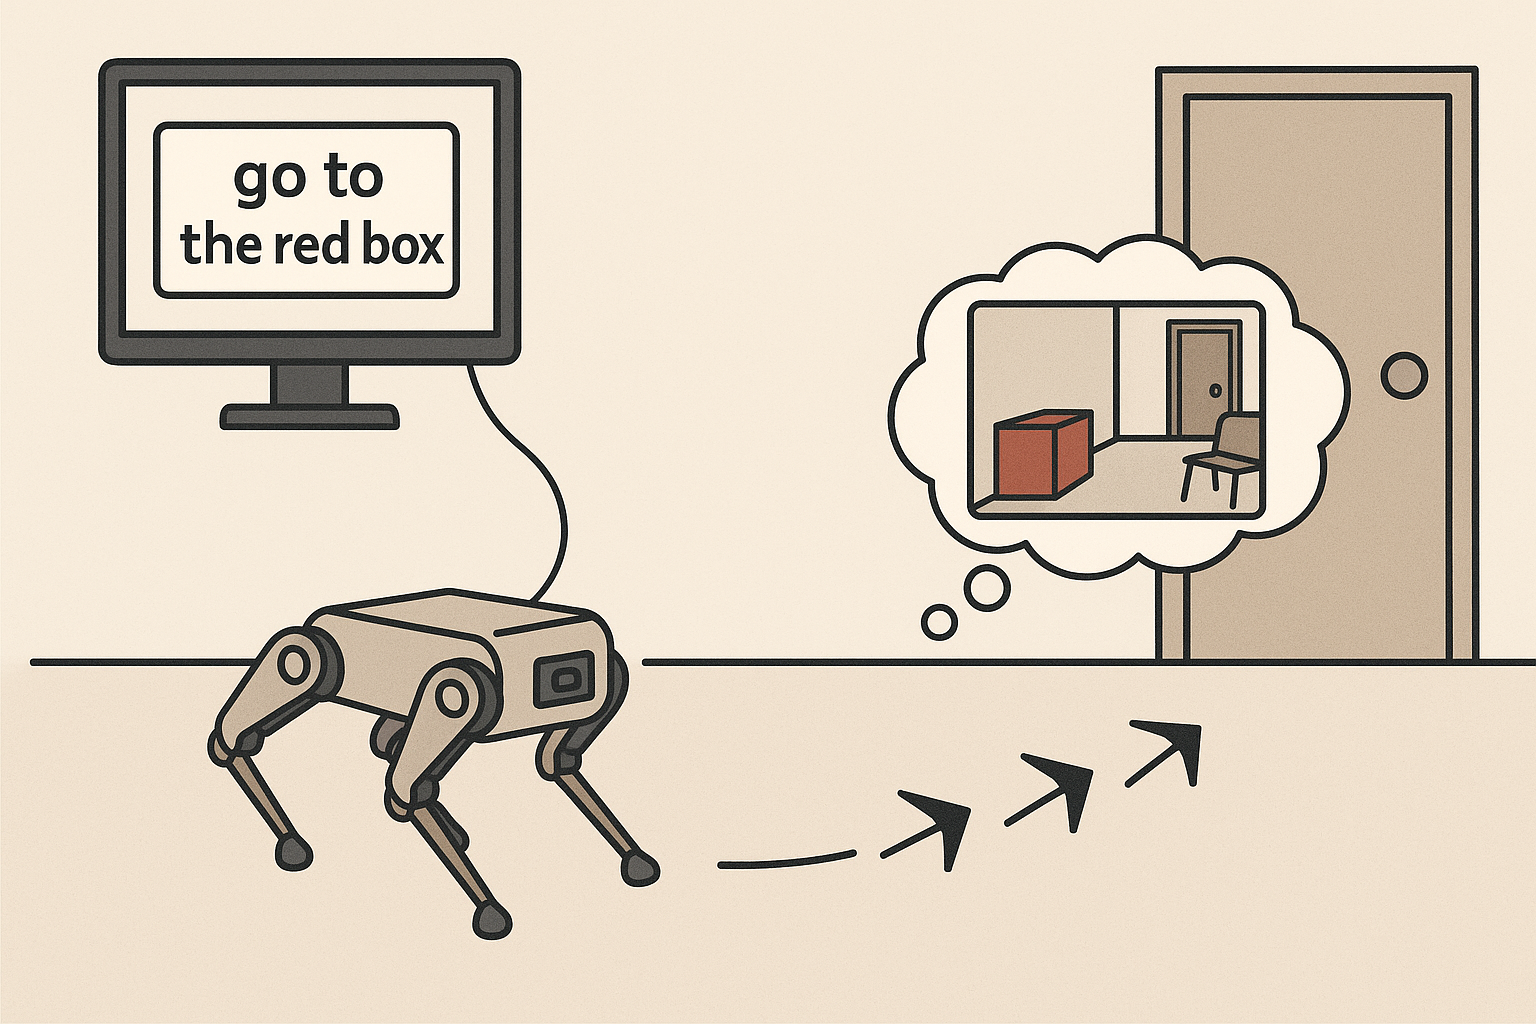
VLAs for Navigation
Introduction Vision-Language-Action (VLA) models have recently emerged as a powerful paradigm for grounding natural-language instructions in perception and control, enabling robots to execute high-level commands specified in human-friendly terms. In this project, we consider a navigation setting in which a mobile robot (Unitree GO2) receives an egocentric RGB-D observation together with a short natural-language instruction (e.g., ‘go to the red box’,’come to the door’) and must output low-level navigation commands (such as velocities or waypoints) that drive it toward the described target [1,2]. Conditioning actions on language offers several advantages over traditional goal specification mechanisms (e.g., manually defined goal coordinates… Read more
-

Quadruped Teleoperation System
Introduction Reinforcement Learning (RL) has recently enabled agile and dynamic behaviors in legged robots. However, RL alone is not always the most suitable tool, especially for sparse, long-horizon tasks that involve complex object manipulation. Even with careful problem formulation, reward design, and curriculum learning, such tasks can remain difficult to solve using standard RL methods. Imitation-based approaches such as Behavioral Cloning, Imitation Learning, and Adversarial Motion Priors (AMP) have emerged as powerful alternatives for these scenarios, as they can leverage existing datasets that demonstrate the desired behavior. These datasets may come from human demonstrations (e.g., videos and teleoperation), optimal controllers,… Read more